A database backup is a photograph of your data at a single moment. Imagine a developer runs a faulty UPDATE statement at 2:45 p.m., and the last backup finished at 2:00 a.m. Restoring that backup brings back clean data, but it also erases almost a full day of legitimate transactions.
Point-in-time recovery (PITR) solves this problem. It combines a database backup with a continuous record of changes, so you can restore a database to a chosen moment, such as the minute before an accidental deletion. This guide explains what PITR is, how it works, how it differs from other recovery methods, and what to check before you rely on it.
What Is Point-in-Time Recovery (PITR)?
Point-in-time recovery (PITR) is a database recovery method that returns data to its exact state at a specific date and time. It works by restoring a full backup and then replaying the changes recorded after that backup, stopping at the target moment instead of at the end of the log. The MySQL reference manual describes the same idea: the binary log files generated after a full backup are the source of information for point-in-time recovery.
The difference from an ordinary restore is precision. A standard restore returns the database to the moment the backup was taken, while PITR lets you choose any moment covered by your backups and logs. You can stop recovery just before a bad transaction instead of losing everything since the last backup.
PITR is also called point-in-time restore or point-in-time database recovery. Vendors name the supporting mechanisms differently (binary logs, write-ahead logs, transaction logs), but the principle is the same: a base backup plus a log of changes.
How Does Point-in-Time Recovery Work?
PITR depends on two assets: a full backup as the starting point, and an unbroken record of every change made after that backup. Recovery rebuilds the database from the first and rolls it forward with the second. Commands differ by engine, but the workflow follows six steps.
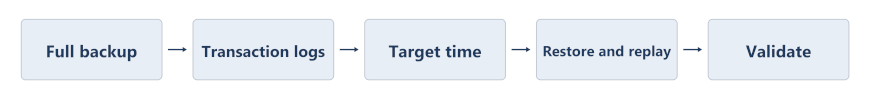
Figure 1. The basic PITR workflow. Log mechanisms and commands vary by database product.
Step 1: Create and Retain a Full Database Backup
Every PITR starts with a full backup older than the target time, and you must keep every log that follows it. PostgreSQL's continuous archiving documentation states the requirement directly: you need a continuous sequence of archived WAL files extending back at least to the start time of your base backup.
Step 2: Capture Transaction Logs or Change Records
While the database runs, it records each change in a log: a binary log (MySQL), write-ahead log or WAL (PostgreSQL), or transaction log (SQL Server). For PITR, these logs must be preserved, not overwritten or discarded. In SQL Server, for example, the database must use the full or bulk-logged recovery model so that log backups are possible.
Step 3: Identify the Target Recovery Time
Decide exactly where recovery should stop. Typical targets are a timestamp just before an accidental DELETE or DROP, the moment before a failed release, or a specific transaction or log position. Use application logs, audit trails, and monitoring alerts to pinpoint the event. A target that is too early discards valid data; one that is too late replays the damage.
Step 4: Restore the Backup
The full backup is restored first. In most engines this leaves the database in a "recovering" state so logs can still be applied. Restoring to a separate server or instance is usually safer than overwriting production, because you can inspect the result first.
Step 5: Replay Logs Until the Target Point
The database applies logged changes in order and stops at the target. In SQL Server, the point-in-time restore procedure uses the STOPAT option on RESTORE LOG, and the recovery point is the latest committed transaction at or before the time you specify. Microsoft also notes a prerequisite: restore a full backup whose end point is earlier than your target, then every subsequent log backup up to the one that contains the target time.
Step 6: Validate Data Integrity and Resume Operations
Before returning the database to service, check that the deleted or corrupted records are in the expected state, that row counts and key tables look correct, and that dependent applications connect and behave normally. Then decide how to reconnect users and reconcile any valid changes made after the target time.
What Are the Key Components of PITR?
Full and Incremental Backups
A full backup is the foundation of recovery. Incremental or differential backups can shorten log replay by moving the starting point closer to the target time, but they supplement the log chain and do not replace it.
Transaction Logs, WAL, or Binary Logs
Logs are the "time machine" in PITR. They hold the ordered record of data changes that the engine replays from the backup to the target time. If a log file is missing or corrupted, recovery can only proceed up to the gap.
Recovery Timestamp and Log Retention
The recoverable window is bounded by the oldest full backup you keep and the newest log you have captured. With seven days of retention, you cannot recover to a point eight days ago, however precise the logs are.
Consistent Backups and Database Integrity
A backup must represent a valid database state that the engine can recover from. Crash-consistent copies may work for some engines, but application-consistent backups, which coordinate with the database engine, are a more reliable starting point for log replay.
Point-in-Time Recovery Example: Recovering a Database After Accidental Deletion
The following timeline is illustrative. Actual precision and steps depend on the database product and configuration.
Time | Event |
14:00 | A full backup completes. Transaction logging is enabled and logs are archived. |
14:00 to 14:45 | Users keep writing data. Every change is recorded in the transaction log. |
14:45 | An administrator accidentally deletes a production table. |
14:50 | The team notices the problem and stops writes to the affected database. |
14:55 | The team restores the 14:00 backup to a separate instance and replays logs up to 14:44:59. |
15:10 | The team verifies the recovered table and copies the data back to production. |
Two lessons stand out. Replay brought the 14:00 backup forward by 44 minutes, so almost nothing was lost before the error. But recovering to 14:44:59 also discards legitimate changes committed between 14:45 and 14:50. That is why teams often recover into a separate instance, extract only the damaged data, and merge it back.
PITR vs. Full Backup vs. Incremental Backup vs. Snapshots
These methods are related but solve different problems. PITR does not replace any of them, because it depends on at least one full backup and a complete log chain.
Method | Recovery precision | What it needs | Typical limitation |
Full backup | The moment the backup was taken | One complete backup copy | Changes since the backup are lost; large and slow to repeat often |
Incremental backup | The moment of the latest incremental run | A full backup plus all incrementals in the chain | Restore requires the whole chain; precision limited to backup intervals |
Storage or VM snapshot | The moment the snapshot was taken | Snapshot support on the storage or hypervisor layer | May not be application-consistent; often stored on the same system as the source data |
Point-in-time recovery | Any moment within the retained log window | A full backup plus a continuous, unbroken log chain | Needs log retention and capture, more storage, and more careful recovery planning |
A snapshot is quick to create and revert, but its recovery value depends on whether it captures the database in a consistent state and is stored independently of the primary system. A snapshot kept on the same storage as the database offers little protection if that storage fails.
Which Databases Support Point-in-Time Recovery?
Most mature database engines support PITR, but each uses its own terminology, settings, and commands. Do not apply one engine's procedure to another.
MySQL: Binary Log-Based Recovery
MySQL restores a full backup and then applies events from the binary log with the mysqlbinlog utility. Binary logging must be enabled, and the official MySQL guide to PITR with the binary log explains how to locate log files and apply events up to a chosen time or position.
PostgreSQL: WAL-Based Recovery
PostgreSQL combines continuous archiving of write-ahead log files with a base backup. According to the PostgreSQL documentation on continuous archiving and PITR, the database can be restored to its state at any time since the base backup was taken. The same page notes that pg_dump and pg_dumpall cannot be part of a continuous-archiving solution, and that WAL archiving does not restore manually edited configuration files.
SQL Server: Transaction Log-Based Recovery
SQL Server supports point-in-time restores for databases in the full or bulk-logged recovery model. Under the bulk-logged model, if a log backup contains bulk-logged changes, recovery to a point inside that backup is not possible, as the Microsoft Learn documentation explains.
Managed Cloud Databases: Service-Specific PITR
Managed services usually automate log capture and expose PITR as a restore option. With Amazon RDS, for example, you can restore a DB instance to a specified time, which creates a new DB instance without modifying the source. The console shows the earliest and latest restorable times, and the service limits what you can change, such as the recovery model for SQL Server. Always check your provider's retention window and restore behavior.
What Are the Limitations and Best Practices of PITR?
PITR is powerful, but it is only as reliable as the backups and logs behind it.
Log Retention and Backup Availability
Keep logs for at least as long as your recovery window requires, and confirm that they are continuous. A single missing log file can stop recovery at the gap. Monitor archive jobs, and alert when log shipping or log backups fail.
Recovery Time, Storage, and Operational Complexity
Replaying a long log chain takes time, and recovery time grows with the volume of changes since the base backup. Logs also consume storage, and a busy database can generate a lot of them. Frequent full or incremental backups shorten the replay window at the cost of more backup storage.
Operational complexity is another factor. Teams that run several database engines often maintain different scripts and procedures for each one. Dedicated backup software can consolidate this work; one example is described later in this guide. Whichever tool you choose, confirm that your database version and recovery model are supported.
Protecting Backups and Logs Against Ransomware
Attackers often target backups and logs along with production data. Store backups and archived logs separately from the database server, restrict who can delete them, encrypt them, and consider immutable or offline copies. A log archive that sits on the compromised server is not a recovery asset.
Testing Recovery Procedures and Verifying RPO/RTO
A recovery procedure you have never tested is an assumption. Run regular restore drills and measure two numbers: the recovery point objective (RPO), which is how much data loss is acceptable, and the recovery time objective (RTO), which is how long the system can stay unavailable. The U.S. National Institute of Standards and Technology covers recovery planning in its Contingency Planning Guide for Federal Information Systems (SP 800-34 Rev. 1), a useful reference for setting and testing recovery objectives.
Application Consistency and Dependent Services
Recovering a database to 14:44:59 does not recover everything around it. Message queues, caches, search indexes, and other databases may hold data from a different moment. Identify these dependencies in advance, and plan how to reconcile them after a restore.
Common PITR Failure Scenarios and How to Avoid Them
Official documentation describes several ways a point-in-time recovery can stall or stop at the wrong place. The table summarizes five, based on the PostgreSQL recovery target settings, the SQL Server recovery models page, and the MySQL manual on recovery using event positions.
Scenario | What happens | How to avoid it |
Archive ends before the target (PostgreSQL) | If archive recovery ends before the configured target is reached, the server shuts down with a fatal error. | Keep the WAL archive continuous through the target time, and monitor archiving. |
Simple recovery model (SQL Server) | The simple model does not support transaction log backups, so there are no logs to replay. | Use the full or bulk-logged recovery model before taking the backups you will rely on. |
Bulk-logged changes in a log backup (SQL Server) | Recovery to a point inside a log backup that contains bulk-logged changes is not possible. | Know which log backups contain bulk operations, or use the full recovery model. |
Stopping by datetime (MySQL) | A datetime identifies only a moment, so events in the same second can be included or excluded. The manual advises against using datetimes to define the replay range. | Use datetimes to find event positions, then replay with start and stop positions. |
Target boundary (PostgreSQL) | With recovery_target_inclusive on (the default), a transaction committed exactly at the target is included. | Set it to off to stop just before the target, and use the pause action to check the result. |
PITR Readiness Checklist
Use this list to check whether a database environment can support point-in-time recovery. Each item reflects a requirement covered earlier in this guide.
1. Full backups are taken regularly and retained at least as long as your recovery window requires.
2. The logging that PITR needs is on: binary logging in MySQL, WAL archiving in PostgreSQL, or the full or bulk-logged recovery model with log backups in SQL Server.
3. Transaction logs, WAL, or binary logs are archived continuously, and failed archive jobs raise alerts.
4. The log chain is unbroken from the base backup to the latest log.
5. Log retention covers how far back you may need to recover.
6. Backups and logs are stored separately from the database server.
7. An immutable or offline copy exists, and permission to delete backups is restricted.
8. Restores are tested regularly on a separate instance, and RPO and RTO are measured.
9. Dependent systems such as caches, queues, and search indexes are documented, and a runbook exists for each database engine.
How Vinchin Backup & Recovery Supports Database PITR
Vinchin Backup & Recovery is a backup product that includes a database module. It backs up SQL Server, Oracle, MySQL, PostgreSQL, TiDB, PostegresPro, and MariaDB databases with application-consistent capabilities and can restore to the original host or a new host.
The component that matters for PITR is its log backup feature. It captures transaction logs or archived redo logs as a sequential log chain, stores only the changes made since the last backup, and lets you restore a database to a specific point between backup intervals.
The SQL Server workflow below follows Vinchin's SQL Server backup tutorial and point-in-time recovery guide. Menu names can differ between product versions, so check the documentation for your release.
1. Install the lightweight Vinchin agent on the SQL Server host.
2. Create a database backup job, select the SQL Server database or instance, and choose the backup storage. Note that a full backup is needed before transaction log backups.
3. Select the "Full Backup and Log Backup" strategy and submit the job.
4. When recovery is needed, choose the database restore option, select a restore point and the target instance, set the restore strategy, and submit.
5. Validate the recovered data before reconnecting applications.
Two other documented features line up with practices covered earlier. Vinchin lists backup copy to a secondary storage location and backup encryption among its features, and its database protection page describes automated recovery drills to help verify that backups can be restored.
Frequently Asked Questions About Database PITR
Q1: What is the difference between PITR and a database restore?
A standard restore returns the database to the state of a backup. PITR restores a backup and then replays logged changes to reach a chosen moment after that backup.
Q2: Can you recover a database to a specific second?
Often yes, but precision depends on the engine and how the log records time. The MySQL manual cautions that a datetime identifies only a moment, so events in the same second can be included or excluded, and it recommends event positions for exact stops. PostgreSQL can stop at a time, a transaction ID, a log sequence number (LSN), or a named restore point.
Q3: Does PITR require a full backup?
Yes. PITR needs a full (base) backup as the starting point, plus every log generated after it. Without that base, there is nothing for the logs to be applied to.
Q4: Can PITR recover deleted tables or records?
Yes, if the deletion occurred within the recoverable window. Restore to a moment before the deletion, preferably on a separate instance, and then copy the data back.
Q5: Is PITR enough for disaster recovery?
No. PITR addresses data loss and logical errors, but disaster recovery also covers hardware failure, site loss, and service continuity. Combine PITR with offsite copies, tested runbooks, and defined RPO and RTO targets.
Conclusion
Point-in-time recovery turns a backup from a single restore point into a continuous timeline. It requires a full backup, an unbroken log chain, adequate retention, and a recovery procedure that has been tested. Take stock of your setup: Are logs being captured? How long are they kept? Where are they stored? Have you tried a restore recently? Answering these questions now is far cheaper than discovering the gaps during an incident.